🔍 Read the full analysis: The Numbers Behind Z.ai’s Legal AI: About 1 In 5 Tasks Passed, Near-Top Rank on ThorstenMeyerAI.com

Get business pricing on monitors, keyboards and dev gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
TL;DR
Z.ai’s GLM-5.3-FlashX-Legal achieved a 19.17% all-criteria pass rate on Vals AI’s version of Harvey’s Legal Agent Benchmark, placing seventh among 81 models on the archived leaderboard. It passed 92.5% of individual criteria, but a task counts as complete only when every criterion passes. The score is independently evaluated; Z.ai’s claim that the model leads open-source systems is not supported by a clearly identified comparison set in the cited material.
Z.ai’s GLM-5.3-FlashX-Legal achieved a 19.17% all-criteria pass rate on Vals AI’s leaderboard for Harvey’s Legal Agent Benchmark, ranking seventh among 81 models in the archived results. The score means the model met every rubric requirement on roughly one in five tested tasks, a demanding measure that matters for legal work where a missed citation, deadline or material issue can leave a work product incomplete.
The archived leaderboard lists the model as GLM Legal, with a score of 19.17% and a reported evaluation cost of $0.15 per test. Z.ai’s documentation rounds the result to 19.2% and says the result was independently evaluated by Vals. The benchmark’s private holdout set contains 120 tasks, according to Vals’ description. Internet access is disabled during the tests, and two language-model judges grade submissions; their task pass rates are averaged.
The score uses an all-or-nothing rule: every rubric criterion must pass for a task to count as complete. Vals also reports that GLM Legal met 92.5% of individual criteria in the archived results. That higher figure measures partial criterion-level performance, not the share of tasks completed in full. A model can satisfy most requirements and still fail the task-level measure if one required item is wrong or absent.
Z.ai says the result is an improvement of 12.5 percentage points over its GLM-5.3-Flash base model. The archived table lists the base model at 6.67%; subtracting that figure from GLM Legal’s 19.17% gives 12.50 percentage points. Z.ai also calls the result state of the art among open-source models in the evaluation. The cited materials do not specify the comparison set behind that claim, and the source report says it found no published weights for the legal model.
A Strict Measure of Legal Task Completion
The result highlights a gap between partial accuracy and complete legal work. A 92.5% criteria pass rate may sound high, but the benchmark’s all-pass rule treats each task as unfinished if even one required element fails. In practice, legal work products often depend on several linked details, including relevant facts, authorities, recommendations and deadlines. The task score is designed to reflect whether the full deliverable meets its rubric, rather than whether most of its pieces are present.
For law firms and legal departments, the ranking is one data point, not evidence that the model can safely work without review. It may help buyers compare systems on a shared evaluation, while leaving practical questions about citation checking, data handling and human supervision unresolved. The low reported cost per test is also not the same as the total cost of deployment, which can include model use, connected data services, review time and safeguards.
The result also calls for care when comparing rankings. GLM Legal’s seventh-place position and 19.17% score refer to a particular archived leaderboard and benchmark version. A position on that table does not establish performance across every type of legal matter, jurisdiction or firm workflow.
Products Worth Considering
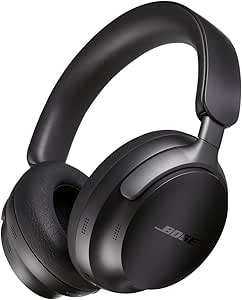
Bose QuietComfort Ultra Wireless Over-Ear Headphones with Spatial Audio and Noise Cancellation, Black

LG UltraGear 32-inch Curved QHD Gaming Monitor (2560×1440, 180Hz, 1ms, 1000R, HDR10)

Logitech MX Master 4 Ergonomic Wireless Mouse with Haptic Feedback, Graphite
As an affiliate, we earn on qualifying purchases.
How Harvey Scores Legal Agents
Harvey released its Legal Agent Benchmark as open source on May 6, 2026. Its task set covers 24 legal practice areas and includes 1,250 public tasks, graded against more than 75,000 expert-written rubric criteria. Each task gives an agent an instruction and client-matter materials, then asks it to produce a work product for review. The leaderboard uses a private holdout set intended to mirror the public task mix.
Harvey’s published grading rule makes the distinction between an individual criterion and a completed task central to interpreting results. Its example is a deal-team report that identifies eight of ten risks: the report may have substantial partial credit, but the task does not pass under all-pass grading. Harvey’s initial baseline, published May 26, reported a best overall all-pass score of 7.1% among the frontier models it tested and said those systems completed fewer than 10% of tasks end to end in aggregate. That was a separate run, so it should not be treated as a direct comparison with the later Vals leaderboard.
Z.ai describes GLM-5.3-FlashX-Legal as a model built on GLM-5.3-Flash and tuned for legal document understanding, reasoning and task execution. Its October 13 blog post announced an application-based beta; Vals lists the release as October 12. Z.ai says the model received legal-domain training and recommends using it as an agent connected to services for laws, cases and company information.
“A task is marked complete only if every criterion passes.”
— Harvey, describing its all-pass grading rule
Limits of the Published Results
The leaderboard score is based on 120 private holdout tasks, not the full 1,250-task public release, and reflects the benchmark’s chosen practice-area mix and grading method. The material supplied does not provide a breakdown of GLM Legal’s results by practice area, task type or error category, so readers cannot tell which legal workflows drove its successes or failures.
The Z.ai documentation page is undated, and the source report says it found no publicly released weights for the legal model. Z.ai’s claim of state-of-the-art performance among open-source models also lacks a named comparison set in the cited documentation. In addition, the benchmark’s two AI judges and their averaged scores are part of the evaluation method; the supplied material does not establish how those scores compare with expert human review of the same submissions.
A separate four-task spot check described in the source report found that the legal model cited rulings the reviewer could not locate. The sample was too small to establish a general error rate. The report also says two Claude models cited a real ruling for the opposite of its holding, illustrating that citation risks are not unique to one system. These observations are not benchmark findings and should not be read as a controlled comparison.
What Firms Should Verify Before Use
Z.ai announced an application-based beta through its AutoClaw blog, but the supplied material does not give a schedule for broader availability or a further benchmark release. Buyers and researchers will need updated leaderboard results and clearer documentation to determine whether the ranking holds across later versions and different legal tasks.
For firms testing the system, the immediate questions are practical: where client information is processed, what rules govern retention and access, which legal databases the agent can consult, and who checks citations and other outputs before they reach a client or court. Z.ai describes the model as supporting drafts for legal professionals; the available material does not establish that those drafts can replace professional review.
Key Questions
What does the 19.17% score mean?
It is the share of benchmark tasks on which the model passed every required rubric criterion, averaged across the evaluation judges. A task with one or more failed criteria does not count as complete.
Why is the criteria pass rate higher at 92.5%?
The 92.5% figure measures individual criteria passed, not whole tasks completed. A model can pass many parts of a task and still miss the all-criteria threshold.
Where did GLM Legal rank?
Vals AI’s archived leaderboard, updated October 18, 2026, listed GLM Legal seventh of 81 models at 19.17%.
Does the result prove the model leads open-source legal AI?
No. Z.ai describes its result as state of the art among open-source models, but the cited material does not identify the comparison set. The source report also says it found no published weights for the legal model.
Can law firms use the model without checking its work?
The benchmark does not establish that. Its task pass rate is below 20%, and the supplied material describes the system as producing drafts for legal professionals. Firms still need to assess data handling, citation accuracy and human review before deployment.
Source: ThorstenMeyerAI.com